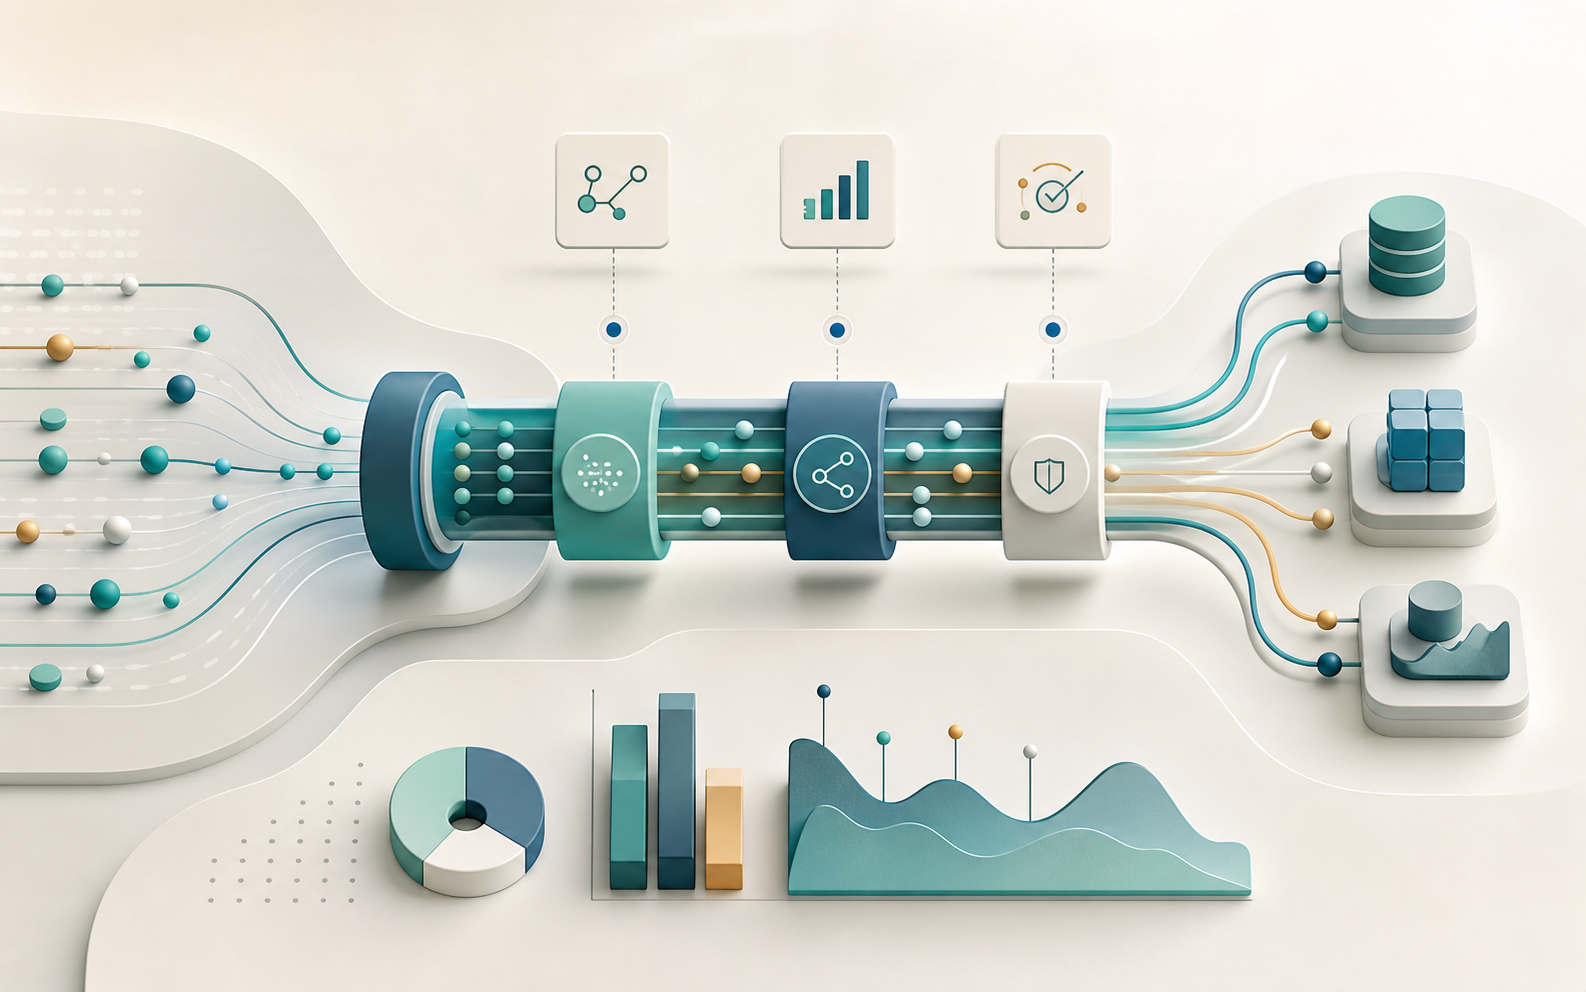
Kafka is powerful when the pipeline has clear product boundaries.
Kafka can move high-volume events between systems, but it does not automatically create a good data architecture. The value comes from clear topics, predictable consumers, recovery rules, and operational ownership.
Treat Kafka as part of the product platform, not just infrastructure. The events should reflect real business moments that downstream systems can understand.
Choose the events other systems need, then make them reliable and easy to trace. Give someone responsibility for what each event means.
1. Use specific topics.
Vague topics create noisy consumers and unclear ownership. Prefer topics that describe a stable event family. A consumer should be able to subscribe without guessing which messages matter.
2. Design partitions around throughput and ordering.
Partitions help parallelize consumers, but they also shape ordering guarantees. If ordering matters for an account, order, shipment, or user, choose the partition key intentionally and document the tradeoff.
3. Make recovery behavior explicit.
Failures happen. Consumers need clear rules for retrying, seeking, dead-letter handling, and idempotency. Without that, a temporary outage can become duplicate records, missing analytics, or stalled workflows.
4. Treat ordering as a business constraint.
Some systems need strict ordering and others do not. Over-ordering can limit throughput. Under-ordering can corrupt downstream assumptions. Decide based on the business process, not a default technical preference.
5. Plan replication and observability together.
Replication protects availability, but observability protects operations. Track lag, failure rates, consumer health, message volume, and dead-letter queues so the team can spot stalled or failing work before customers are affected.
Who owns the event contract?
Make it clear who owns each event contract and how changes reach its consumers. Without that, a pipeline can hide the connections teams need to understand before making a change.
Related insights